
Camera Setup & Object Detection — Research 2
SAM 3 instance segmentation, mask generation from object-detection prompts, CPU performance benchmarks, and edge refinement.
Research 2: Object Detection & SAM 3 Segmentation
Converting classroom images into structured object detections, then refining each bounding box into a pixel-level segmentation mask for tracking, inventory, and scene comparison.
Individual research by Shriya Paladugu
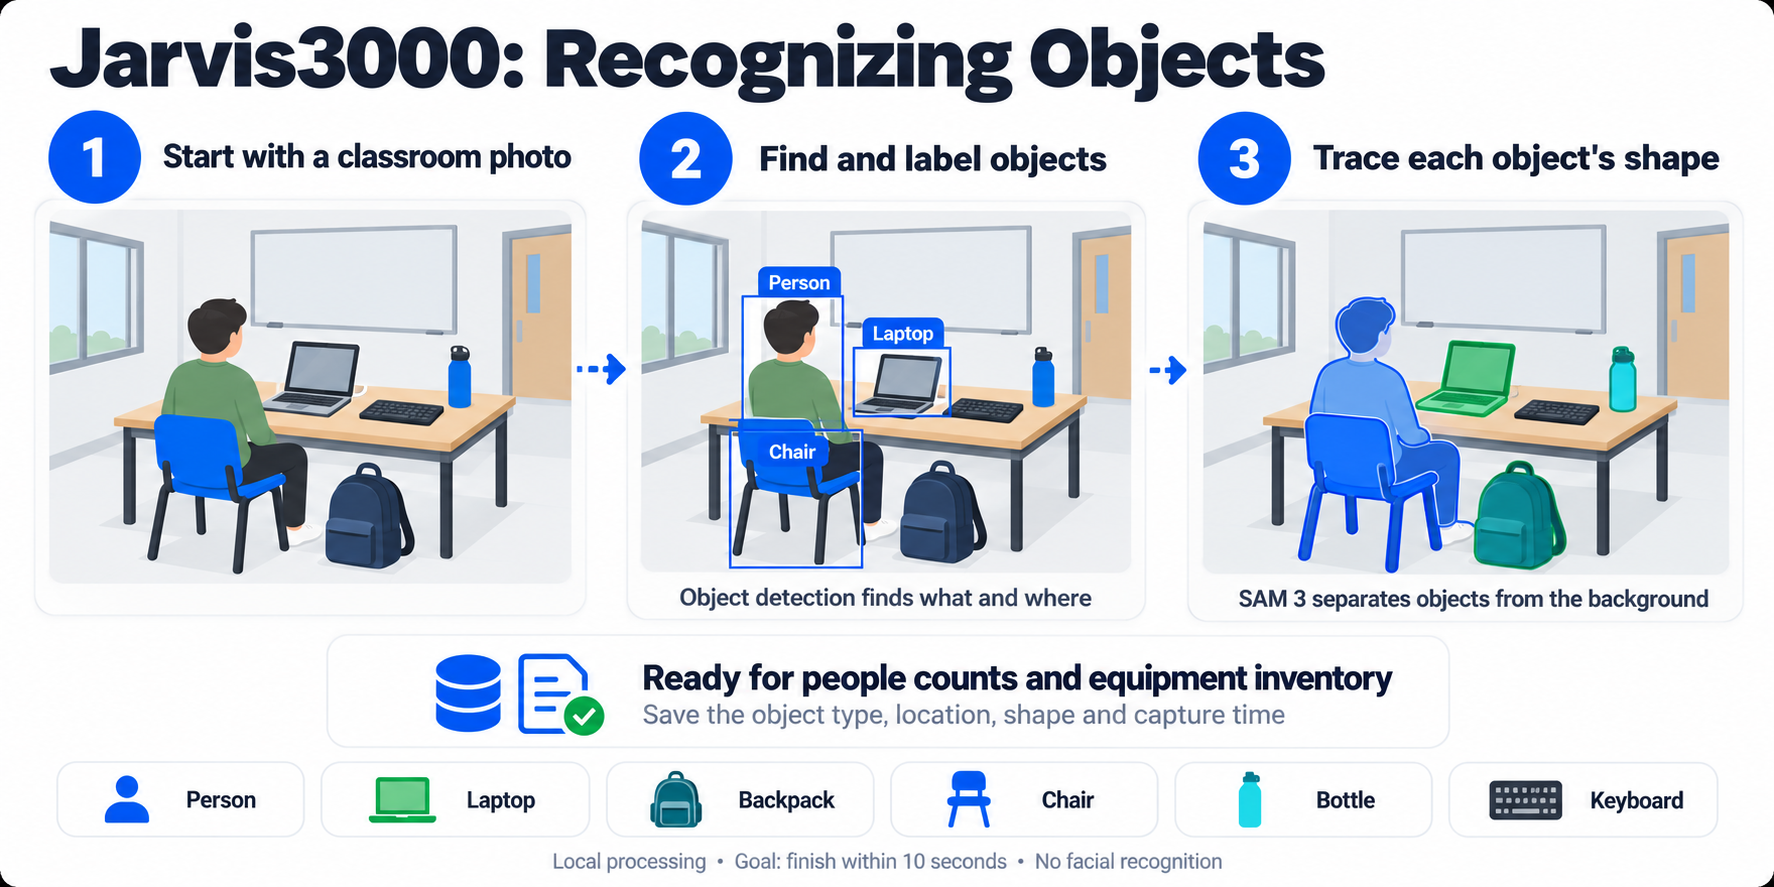
Problem Statement
A classroom is a constantly changing environment where people and equipment enter, leave, or move locations. A camera records pixels, but raw images alone do not tell the system what objects are present or where each object appears. The project therefore needs a computer-vision pipeline that identifies classroom objects, records their confidence scores and image locations, and separates them from the surrounding background.
Research Question 2
How accurately and efficiently can a locally executed object-detection and SAM 3 pipeline detect, classify, locate, and segment important classroom objects under changing lighting, viewing angles, distance, and partial occlusion while remaining within the target 10-second processing cycle?
Role in the Full System
flowchart TD
    CAP["Camera capture\nTimestamped frame"] --> PRE["OpenCV / FFmpeg\nResize + preprocessing"]
    PRE --> DETECT["Object detector\nClass + confidence + box"]
    DETECT --> SAM["SAM 3\nPixel-level mask"]
    SAM --> OUT["Structured observation\nDetection + mask + timestamp"]
    OUT --> TRACK["Tracking / inventory /\nscene comparison"]
Initial Target Object Classes
The initial prototype will evaluate six common classroom classes that can support people counting and basic equipment inventory.
Supports occupancy counting without facial recognition.
Represents portable classroom hardware.
Tests detection of personal items and partial occlusion.
Provides a frequent, repeated furniture class.
Tests small-object detection at different distances.
Tests recognition of specialized desk equipment.
Detection Output
Instead of passing only raw images to later components, the pipeline creates a structured observation for every detected object.
{
  "timestamp": "2026-09-07T10:15:20.000Z",
  "camera_id": "camera_1",
  "class": "laptop",
  "confidence": 0.94,
  "bounding_box": [120, 80, 420, 350],
  "mask_reference": "camera_1_20260907_101520_laptop_01"
}
Model Selection & Technical Rationale
Recognizes multiple objects in one frame and returns a class label, confidence score, and bounding box for each detection.
Allows early testing on common objects before collecting a large custom dataset.
Can be introduced if pretrained classes do not recognize specialized classroom equipment reliably.
Uses detector boxes as prompts and produces masks that preserve object shape more precisely than rectangles.
Keeps classroom data on the Linux host and avoids continuous cloud upload.
Compares 720p and 1080p inputs to balance small-object detail against CPU latency.
Why Object Detection Instead of Image Classification?
A standard image-classification model can predict that a classroom image contains a laptop, but it does not identify every separate laptop or show where each one is located. An object-detection model performs both classification and localization, allowing the system to detect multiple objects in one frame and return an individual class label, confidence score, and bounding box for each object. This makes object detection more suitable for classroom inventory, people counting, tracking, and scene comparison.
Acceptance Criteria & Test Cases
- Capture a timestamped classroom frame and return a class label, confidence score, and bounding box for every accepted object detection
- Evaluate all six target classes using a separate held-out test set that was not used for training
- Reach the project target of at least 80% correct-class detections on the held-out images and also report per-class precision, recall, and mAP50
- Compare detection performance under bright light, reduced light, distance, unusual viewing angles, and partial occlusion
- Pass detector bounding boxes to SAM 3 as prompt boxes and generate a binary mask for each selected object
- Measure mask quality using Intersection over Union on a manually labeled validation sample
- Measure end-to-end object-detection and SAM latency at 720p and 1080p on the actual Linux host
- Complete one capture-and-processing cycle within 10 seconds, or document the optimization needed to reach that target
Compute Constraints & Benchmark Plan
| Resolution | What Will Be Measured | Expected Tradeoff | Status |
|---|---|---|---|
| 720p (1280×720) | Detector latency, SAM latency, total cycle time, class metrics, mask IoU | Faster processing but reduced detail for small or distant objects | TO TEST |
| 1080p (1920×1080) | Detector latency, SAM latency, total cycle time, class metrics, mask IoU | More object detail with increased CPU and memory demand | TO TEST |
| 4K (3840×2160) | Optional comparison if lower resolutions cannot preserve required detail | Highest input detail but likely to exceed the CPU time budget | OPTIONAL |
Open Questions & Next Steps
- Baseline Test: Determine which target classes are already supported reliably by the selected pretrained object-detection model.
- Dataset: Collect representative classroom images across both camera viewpoints and split them into training, validation, and held-out test sets.
- Fine-Tuning: Train a custom model only for classes that do not meet the required detection performance.
- Prompt Refinement: Test box prompts and optional positive/negative points when adjacent objects cause SAM mask leakage.
- Optimization: Evaluate lower input resolution, model-size selection, ONNX Runtime, and quantization if the local pipeline exceeds 10 seconds.
Technical Sources
- Demonstrates pretrained object detectors and the tradeoff between speed and accuracy.
- Provides background for comparing object-detection approaches.
- Describes transfer learning and lightweight local deployment.
- Supports possible custom training for specialized classroom classes.